class AgentConfig:
horizon: int = 6
replan_on_target_move: bool = True
replan_on_obstacle_change: bool = True
max_steps: int = 120
think_latency: float = 0.02
act_latency: float = 0.01
risk_gate: float = 0.85
alt_search_depth: int = 2
@dataclass
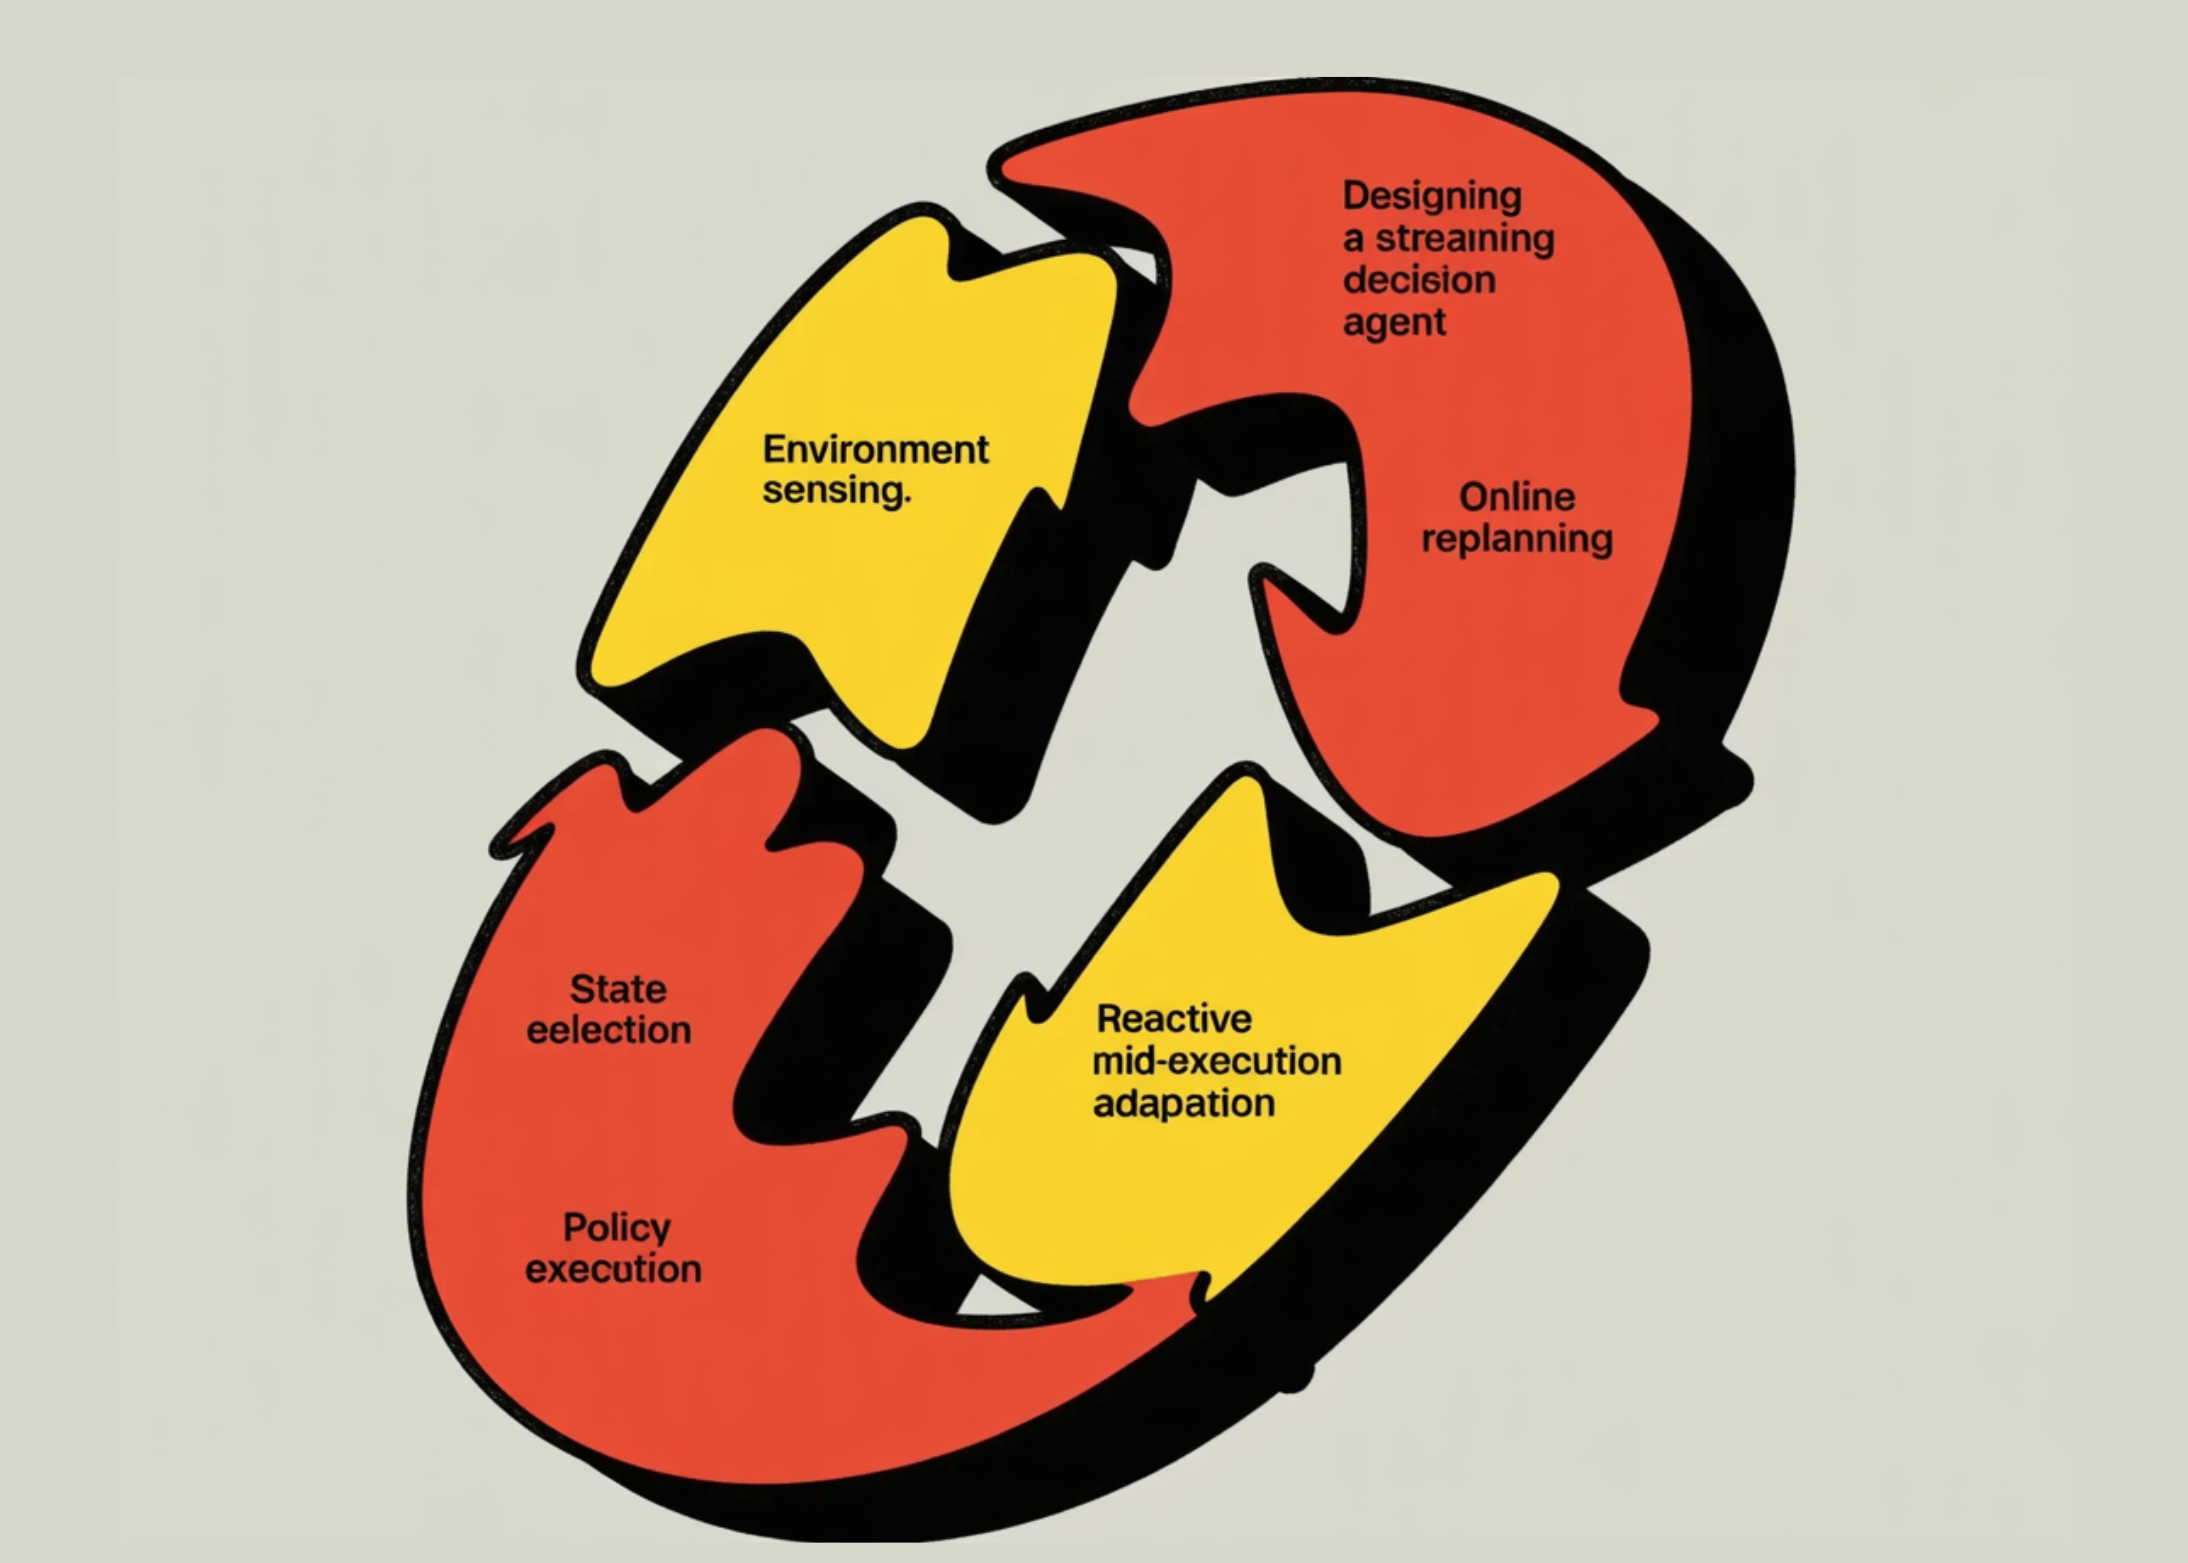
class StreamingDecisionAgent:
cfg: AgentConfig
world: DynamicGridWorld
start_time: float = field(init=False, default_factory=time.time)
step_id: int = field(init=False, default=0)
current_plan: List[Coord] = field(init=False, default_factory=list)
current_actions: List[str] = field(init=False, default_factory=list)
last_snapshot: Dict[str, Any] = field(init=False, default_factory=dict)
stats: Dict[str, Any] = field(init=False, default_factory=lambda: defaultdict(int))
def _now(self) -> float:
return time.time() – self.start_time
def _emit(self, kind: str, msg: str, data: Optional[Dict[str, Any]] = None) -> StreamEvent:
return StreamEvent(t=self._now(), kind=kind, step=self.step_id, msg=msg, data=data or {})

def _need_replan(self, obs: Dict[str, Any]) -> bool:
ch = obs[“changes”]
if obs[“done”]:
return False
if not self.current_plan or len(self.current_plan) <= 1:
return True
if self.cfg.replan_on_target_move and ch.get(“target_moved”):
return True
if self.cfg.replan_on_obstacle_change and (ch.get(“obstacles_added”) or ch.get(“obstacles_cleared”)):
return True
if len(self.current_plan) > 1 and self.current_plan[1] in self.world.obstacles:
return True
return False
def _plan(self) -> PlanResult:
time.sleep(self.cfg.think_latency)
self.stats[“replans”] += 1
return astar(self.world, self.world.agent, self.world.target)
def _choose_action(self, planned_action: str) -> Tuple[str, str]:
ax, ay = self.world.agent
action_to_delta = {“R”: (1,0), “L”: (-1,0), “D”: (0,1), “U”: (0,-1), “S”: (0,0)}
dx, dy = action_to_delta[planned_action]
nxt = (ax+dx, ay+dy)
if not self.world.in_bounds(nxt) or not self.world.passable(nxt):
self.stats[“overrides”] += 1
return “S”, “planned_move_invalid -> wait.”
r = action_risk(self.world, nxt)
if r > self.cfg.risk_gate:
candidates = [“U”,”D”,”L”,”R”,”S”]
best = (planned_action, float(“inf”), “keep_plan”)
for a in candidates:
dx, dy = action_to_delta[a]
p = (ax+dx, ay+dy)
if not self.world.in_bounds(p) or not self.world.passable(p):
continue
score = action_risk(self.world, p) + 0.05 * self.world.manhattan(p, self.world.target)
if score < best[1]:
best = (a, score, “risk_avoidance_override”)
if best[0] != planned_action:
self.stats[“overrides”] += 1
return best[0], best[2]
return planned_action, “follow_plan”
def run(self) -> Generator[StreamEvent, None, None]:
yield self._emit(“observe”, “Initialize: reading initial state.”, {“agent”: self.world.agent, “target”: self.world.target})
yield self._emit(“world”, “Initial world snapshot.”, {“grid”: self.world.render()})
for self.step_id in range(1, self.cfg.max_steps + 1):
if self.step_id == 1 or self._need_replan(self.last_snapshot):
pr = self._plan()
self.current_plan = pr.path
self.current_actions = path_to_actions(pr.path)
if pr.reason != “found_path”:
yield self._emit(“plan”, “Planner could not find a path within budget; switching to reactive exploration.”, {“reason”: pr.reason, “expanded”: pr.expanded})
self.current_actions = []
else:
horizon_path = pr.path[: max(2, min(len(pr.path), self.cfg.horizon + 1))]
yield self._emit(“plan”, f”Plan updated (online A*). Commit to next {len(horizon_path)-1} moves, then re-evaluate.”, {“reason”: pr.reason, “path_len”: len(pr.path), “expanded”: pr.expanded, “commit_horizon”: self.cfg.horizon, “horizon_path”: horizon_path, “grid_with_path”: self.world.render(path=horizon_path)})
if self.current_actions:
planned_action = self.current_actions[0]
else:
ax, ay = self.world.agent
tx, ty = self.world.target
options = []
if tx > ax: options.append(“R”)
if tx < ax: options.append(“L”)
if ty > ay: options.append(“D”)
if ty < ay: options.append(“U”)
options += [“S”,”U”,”D”,”L”,”R”]
planned_action = options[0]
action, why = self._choose_action(planned_action)
yield self._emit(“decide”, f”Intermediate decision: action={action} ({why}).”, {“planned_action”: planned_action, “chosen_action”: action, “agent”: self.world.agent, “target”: self.world.target})
time.sleep(self.cfg.act_latency)
obs = self.world.step(action)
self.last_snapshot = obs
if self.current_actions:
if action == planned_action:
self.current_actions = self.current_actions[1:]
if len(self.current_plan) > 1:
self.current_plan = self.current_plan[1:]
ch = obs[“changes”]
surprise = []
if ch.get(“target_moved”): surprise.append(“target_moved”)
if ch.get(“obstacles_added”): surprise.append(f”obstacles_added={len(ch[‘obstacles_added’])}”)
if ch.get(“obstacles_cleared”): surprise.append(f”obstacles_cleared={len(ch[‘obstacles_cleared’])}”)
surprise_msg = (“Surprises: ” + “, “.join(surprise)) if surprise else “No major surprises.”
self.stats[“steps”] += 1
if obs[“moved”]: self.stats[“moves”] += 1
if ch.get(“target_moved”): self.stats[“target_moves”] += 1
if ch.get(“obstacles_added”) or ch.get(“obstacles_cleared”): self.stats[“world_shifts”] += 1
yield self._emit(“observe”, f”Observed outcome. {surprise_msg}”, {“moved”: obs[“moved”], “agent”: obs[“agent”], “target”: obs[“target”], “done”: obs[“done”], “changes”: ch, “grid”: self.world.render(path=self.current_plan[: min(len(self.current_plan), 10)])})
if obs[“done”]:
yield self._emit(“done”, “Goal reached. Stopping execution.”, {“final_agent”: obs[“agent”], “final_target”: obs[“target”], “stats”: dict(self.stats)})
return
yield self._emit(“done”, “Max steps reached without reaching the goal.”, {“final_agent”: self.world.agent, “final_target”: self.world.target, “stats”: dict(self.stats)})